The short answer
Small language models for enterprise are AI models, usually under 10 billion parameters, that run on one GPU or a laptop and handle narrow, repeatable tasks. They beat frontier models when the job is high-volume, well-defined, privacy-sensitive or speed-critical. For open-ended reasoning, a frontier model still wins.
Key takeaways
- In two years, the model size needed to clear 60% on MMLU fell 142-fold.
- Serving a 7B model is 10 to 30 times cheaper than a 70B to 175B model, per NVIDIA researchers.
- Run four tests per workload: volume, scope, data and speed. Two or more yes answers point to small.
- Keep a frontier model for open-ended work and as the fallback when the small one is unsure.
- Start with logs, not models. Your own call data tells you what to move.
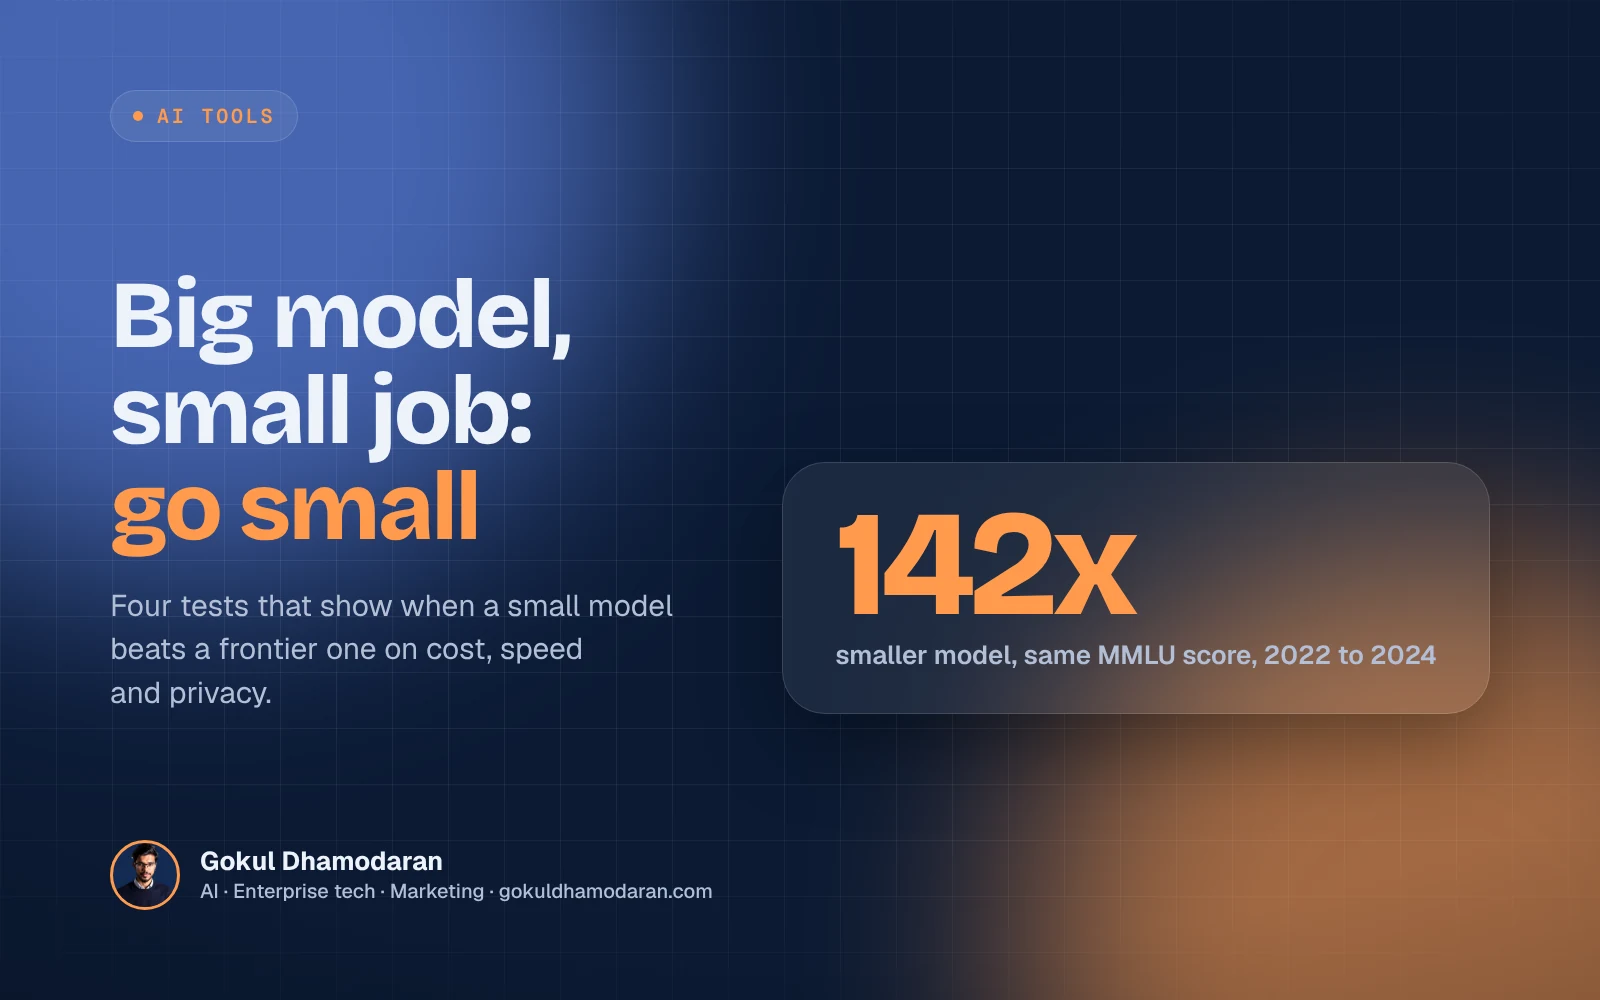
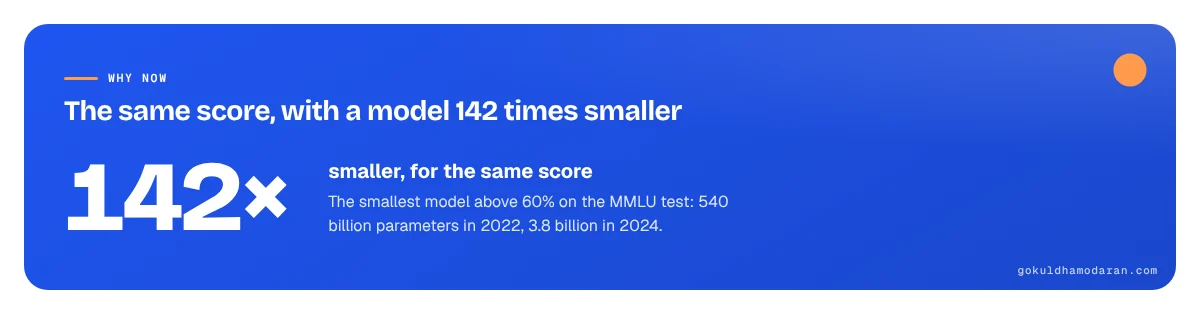
In 2022, the smallest model that scored above 60% on the MMLU knowledge test had 540 billion parameters. By 2024, a 3.8 billion parameter model cleared the same bar. That is a 142-fold drop in two years, per Stanford’s 2025 AI Index, and it changes the math on small language models for enterprise.
Most enterprise AI work is not a philosophy exam. It is sorting tickets, pulling fields from invoices, tagging records and routing requests. Paying frontier prices for that is like sending every parcel by overnight jet. This guide gives you a plain-English view of what small models are, a four-test rule for choosing, and a safe way to move a workload over.
The same score, with a model 142 times smaller
smaller, for the same score
The smallest model above 60% on the MMLU test: 540 billion parameters in 2022, 3.8 billion in 2024.
gokuldhamodaran.com
What are small language models for enterprise?
Small language models for enterprise are language models compact enough to run on a single GPU, a server in your own data center or even a laptop, while handling a defined business task well. NVIDIA researchers define them by what they do rather than a strict size: a model that fits on common consumer hardware and answers fast enough for one user. In practice, that means most models under about 10 billion parameters.
Familiar examples include Microsoft’s Phi family, Google’s Gemma, Meta’s smaller Llama models and NVIDIA’s Nemotron models. Google released Gemma 3 in March 2025 in four sizes, from 1 billion to 27 billion parameters, with a 128,000-token context window and function calling for agent work. Many of these are open-weight, so you can download them and run them inside your own walls.
The point that matters for a CIO: a small model is not a cheaper copy of a big one. It is a specialist. You give up breadth to gain cost, speed and control.
SLM vs LLM: what is real and what is hype?
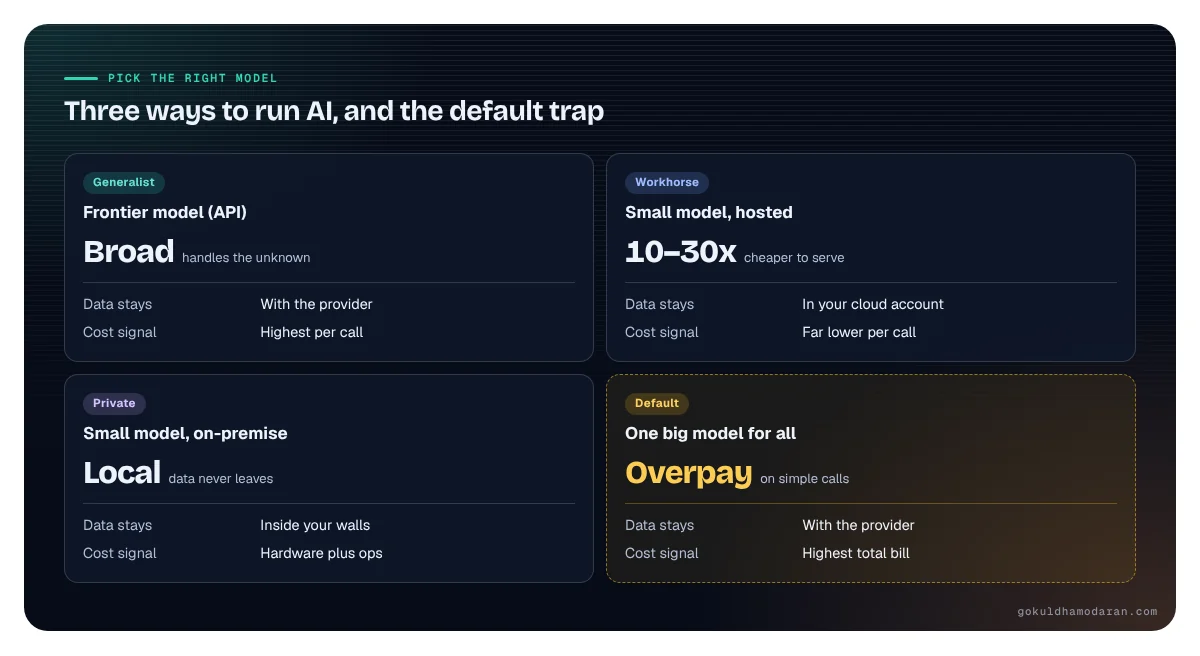
The real part of the SLM vs LLM debate is cost and speed. In their 2025 paper, NVIDIA Research and Georgia Tech estimate that serving a 7 billion parameter model is 10 to 30 times cheaper than a 70 to 175 billion parameter model, measured in latency, energy and compute. Narrow tasks also get more accurate when you tune a small model on your own data.
Analysts see the same shift. In April 2025, Gartner predicted that by 2027 organizations will use small, task-specific AI models at least three times more than general-purpose large language models. Its reasoning was simple: general models lose accuracy on tasks that need specific business context.
The hype part is the idea that small models replace big ones. They do not. Small models know less about the world, follow messy instructions less reliably and can make more mistakes outside their lane. Ask a tuned invoice model to draft a board memo and you will see the limit fast.
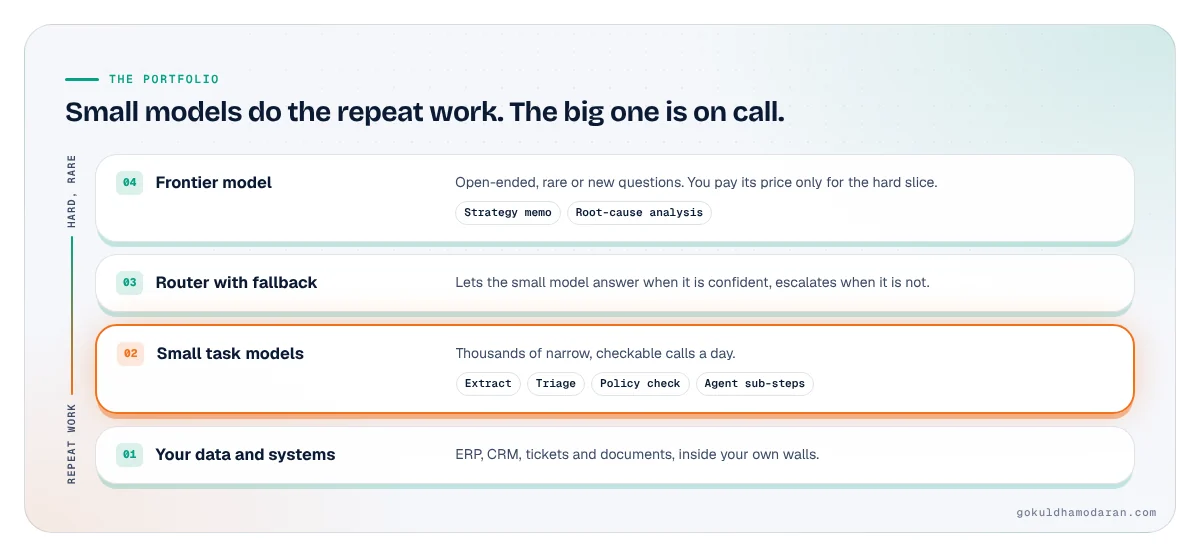
My read: the winning setup is not small or large. It is a portfolio, with a small model doing the repeat work and a frontier model on call for the hard cases.
Three ways to run AI, and the default trap
Frontier model (API)
Small model, hosted
Small model, on-premise
One big model for all
gokuldhamodaran.com
When does a small model beat a frontier model? The four-test rule
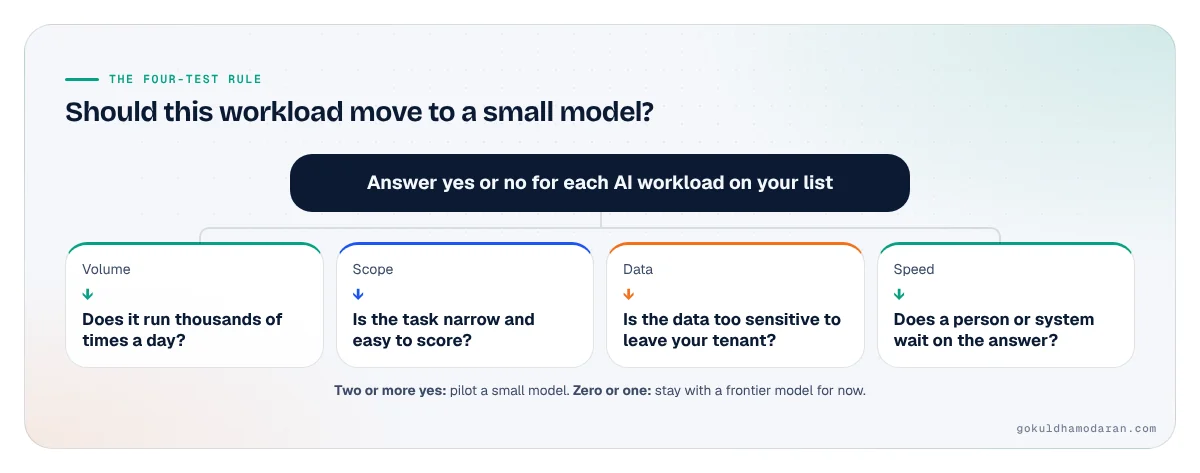
Use this rule for every AI workload on your list. Answer each test with a yes or no. Two or more yes answers mean you should pilot a small model. Zero or one means stay with a frontier model for now.
- Volume: does it run thousands of times a day? Cost per call barely matters for a weekly report. It matters a lot for every email, ticket or invoice that moves through a process. High volume is where a 10x cheaper model pays for its setup.
- Scope: is the task narrow and well defined? Classify, extract, route, summarize to a template, check against a policy. If you can describe a good answer in one paragraph and score it automatically, a small model can learn it.
- Data: is the data too sensitive to leave your tenant? Patient notes, contracts, payroll, source code and pricing often fall here. A small model can run on your own servers or in your own cloud account, so prompts and outputs stay in your control.
- Speed: does a person or a system wait on the answer? Autocomplete in a form, a check inside an approval flow or a step in an agent chain needs answers in a fraction of a second. Smaller models answer faster on cheaper hardware.
The rule works because it ties the model choice to the process, not the vendor slide. It also gives finance a clear reason for each choice, which makes the budget conversation shorter.
Should this workload move to a small model?
Answer yes or no for each AI workload on your list
- VolumeDoes it run thousands of times a day?
- ScopeIs the task narrow and easy to score?
- DataIs the data too sensitive to leave your tenant?
- SpeedDoes a person or system wait on the answer?
Two or more yes: pilot a small model. Zero or one: stay with a frontier model for now.
gokuldhamodaran.com
Which small language model use cases work in production?
The small language model use cases that work in production share one trait: the output has a shape you can check. Here are the patterns I would start with, grouped by where they sit in an enterprise stack.
- Document extraction for ERP: pull vendor, amount, dates and line items from invoices and purchase orders, then hand clean fields to the ERP. Output is a fixed schema, so errors are easy to catch.
- Ticket and email triage: classify incoming requests by type, urgency and team, and route them. A frontier model is overkill for choosing one of twelve labels.
- Policy and compliance checks: flag whether a contract clause, expense or access request matches a written rule, and cite the rule.
- Data cleanup: standardize product names, addresses and job titles across systems before they hit a data warehouse or CRM.
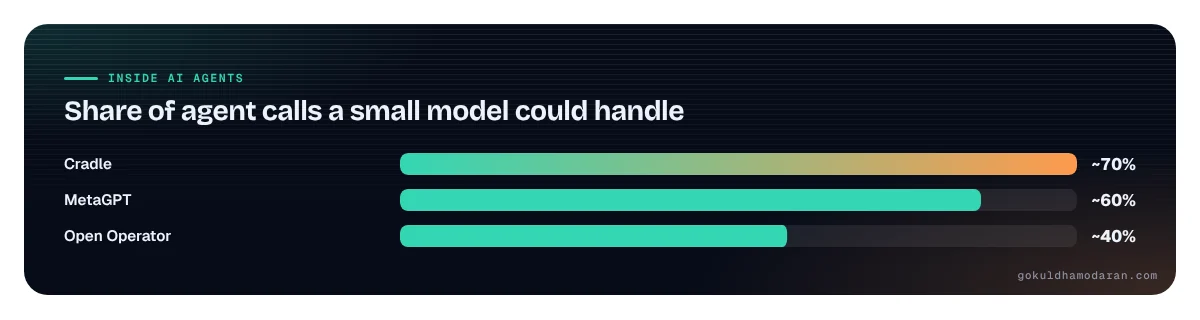
- Agent sub-steps: the repeated tool calls inside an agent, such as formatting a query, picking the next tool or checking a result. NVIDIA’s case studies estimate that small models could handle about 40% to 70% of the model calls in three open-source agent frameworks.
- Offline and edge work: field service, factory floors and retail stores, where connections drop and data must stay local.
Notice what is missing: open-ended strategy, research across many sources and anything where the question changes every time. Those stay with the frontier model.
When should you stay with a frontier model?
Stay with a frontier model when the task is open-ended, rare or changes faster than you can retrain. Think of a strategy memo, a hard root-cause analysis, research across dozens of documents, or a new customer question nobody has seen. These tasks fail all four tests, and the cost of a wrong answer outweighs the token bill.
Also stay big while you are still learning what a workload is. You cannot tune a small model on a task you have not defined. Many teams should run the frontier model first, log every call for a month, and only then decide what to move. That log becomes your training data and your test set.
Finally, keep a frontier model as the fallback. A good production design lets the small model answer when it is confident and escalates to the larger model when it is not. You pay frontier prices only for the hard slice.
Small models do the repeat work. The big one is on call.
- 04Frontier modelOpen-ended, rare or new questions. You pay its price only for the hard slice.Strategy memoRoot-cause analysis
- 03Router with fallbackLets the small model answer when it is confident, escalates when it is not.
- 02Small task modelsThousands of narrow, checkable calls a day.ExtractTriagePolicy checkAgent sub-steps
- 01Your data and systemsERP, CRM, tickets and documents, inside your own walls.
gokuldhamodaran.com
What do on-premise AI models really cost?
On-premise AI models cut the per-call bill to almost nothing, but they move cost into people and hardware. Budget for four lines: GPUs or reserved cloud capacity, an engineer who can serve and monitor models, an evaluation set that you rerun after every change, and time to retrain as your data drifts.
 On-premiseCheap per call. Not free to run.
That is why the volume test comes first. A model that answers a few hundred questions a week rarely justifies its own servers. A model in the path of every invoice or ticket usually does. If you are unsure, start with a small model hosted in your existing cloud account. You get most of the privacy benefit without buying hardware.
Two other costs are easy to miss. First, licenses: open-weight does not always mean free for every commercial use, so have legal read each model’s terms. Second, security: a model you host is now part of your attack surface, with the same patching and access rules as any other system. Check the details with your legal and security teams before you commit.
From the bench: when I build analytics that answer business questions in plain English, the hard part is never the size of the model. It is showing the query behind every number so a finance lead can check it. Small models make that easier to afford, but the checking still has to be designed in.
How do you move a workload from an LLM to a small model?
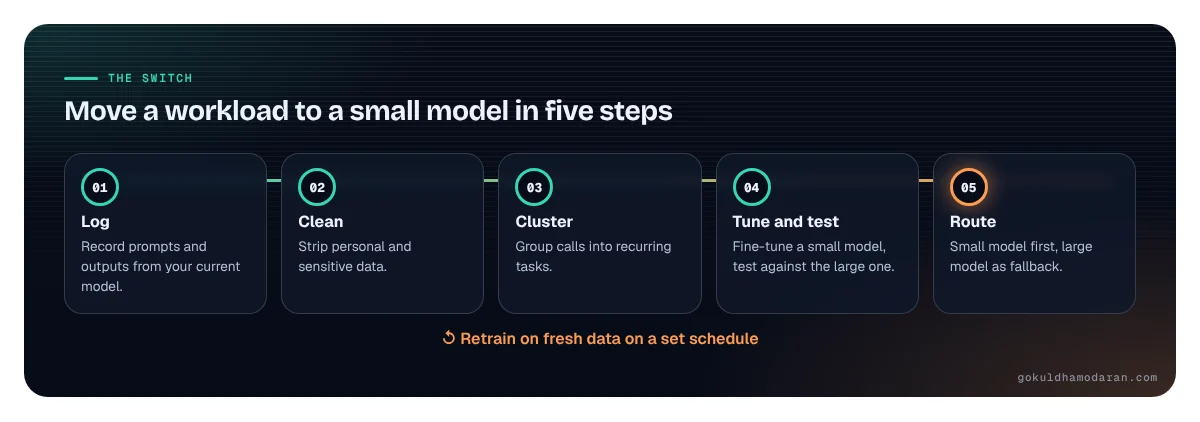
You move a workload by starting from your own usage logs, not from a model leaderboard. The NVIDIA paper outlines a conversion loop that works well as a project plan. Here it is in plain steps.
- Log the calls. Record the prompts and outputs your current AI features send to the large model, with encryption and access controls.
- Clean the data. Remove personal, health and other sensitive data before anyone uses the logs for training.
- Cluster the tasks. Group the calls into recurring jobs. You will often find a handful of tasks make up most of the volume.
- Pick candidates. For each big cluster, shortlist two or three small models based on accuracy on your test set, license terms and hardware footprint.
- Fine-tune and test. Tune the best candidate on your examples, using light methods such as LoRA. NVIDIA’s rule of thumb is 10,000 to 100,000 examples. Compare it with the large model on the same test set.
- Route and retrain. Send the task to the small model with a fallback to the large one, then retrain on fresh data on a set schedule.
This is also the safest path for governance. Every step leaves a record of what data was used, what the model was tested against and who signed off.
Move a workload to a small model in five steps
- 01LogRecord prompts and outputs from your current model.
- 02CleanStrip personal and sensitive data.
- 03ClusterGroup calls into recurring tasks.
- 04Tune and testFine-tune a small model, test against the large one.
- 05RouteSmall model first, large model as fallback.
↺ Retrain on fresh data on a set schedule
gokuldhamodaran.com
What goes wrong when teams switch to small models?
Most small-model projects that disappoint fail for process reasons, not model reasons. Three mistakes show up again and again.
- No test set. The team swaps the model, spot-checks ten answers and calls it done. A month later an edge case slips into the ERP. Fix it with a fixed set of a few hundred real examples, scored the same way before and after every change.
- No fallback. The small model gets every request, including the strange ones it was never trained on. Fix it by setting a confidence threshold and sending anything below it to the larger model or to a person.
- No owner after launch. Invoice formats change, product names change and new ticket types appear. A tuned model slowly drifts. Fix it by naming an owner who reviews accuracy each month and decides when to retrain.
None of these is hard. They are the same disciplines you already apply to any system that touches finance or customers. The model is small; the operating model around it should not be.
What should enterprise leaders do this quarter?
You do not need a new AI strategy to act on this. You need one list and one pilot. Here is a 30-day plan for a CIO, CTO or head of data.
- Week 1: list every live or planned AI workload and its monthly call volume. Add the owner and what data each one touches.
- Week 2: run the four-test rule on each line. Mark every workload with two or more yes answers.
- Week 3: pick one marked workload with a clear right answer, such as invoice extraction or ticket routing. Build a test set of a few hundred real examples with known answers.
- Week 4: compare a small model against your current model on that test set, then on cost and speed. Bring the three numbers to your steering group.
The adoption lens matters here. Pilots get funded when the business case fits on one slide: same accuracy, lower cost per transaction, data that never leaves your control. A small-model pilot is one of the rare AI projects that can show all three in a month. It is the same lesson I learned running an account-based marketing program: buyers sign off on a measured result, not a promise.
If your stack includes ERP, pair this with your modernization plan. Teams working through the SAP ECC end of maintenance 2027 deadline are rebuilding the same document and approval flows where small models fit best.
The bottom line on small language models for enterprise
Small language models for enterprise are not a trend to wait out. They are the workhorse layer of a sensible AI stack. Let a frontier model do the thinking that needs it, let small models do the high-volume, narrow work, and let your own logs decide which is which.
Signal, not noise: count your calls before you pick your models. I write about AI and enterprise systems every Monday, Wednesday and Friday at gokuldhamodaran.com, and the weekly roundup goes out in the newsletter.
Frequently asked questions
What is the difference between an SLM and an LLM?
A small language model has fewer parameters, usually under about 10 billion, and runs on a single GPU or device. A large language model has tens or hundreds of billions and usually runs in a provider's data center. Small models are cheaper and faster for narrow tasks; large models handle broader, open-ended reasoning better.
Are small language models accurate enough for enterprise work?
For narrow tasks with a clear right answer, often yes, especially after fine-tuning on your own examples. Gartner notes that general models lose accuracy on tasks that need specific business context. Always prove it on a test set of your own real cases before switching, and keep a larger model as the fallback.
Can I run a small language model on my own servers?
Yes. Many small models are open-weight, so you can download and host them on your own hardware or in your own cloud account. That keeps prompts and outputs under your control. Check each model's license for commercial use, and plan for the engineering time to serve, monitor and update it.
How much data do I need to fine-tune a small model?
NVIDIA researchers give a rule of thumb of 10,000 to 100,000 examples for fine-tuning a small model on a task. Many teams already have that volume in the logs of an existing AI feature. Clean out personal and sensitive data first, and hold back a separate test set you never train on.
Do small models work inside AI agents?
They fit well for the repeated sub-steps inside an agent, such as formatting a tool call, picking the next action or checking a result. NVIDIA's case studies estimate small models could handle about 40% to 70% of the model calls in three open-source agent frameworks, with a larger model kept for planning and hard cases.
Sources
- Gartner: By 2027, organizations will use small, task-specific AI models three times more than general-purpose LLMs (Apr 2025)
- NVIDIA Research and Georgia Tech: Small Language Models are the Future of Agentic AI (2025)
- Stanford HAI: AI Index Report 2025, technical performance chapter
- Google: Introducing Gemma 3 (Mar 2025)
Gokul Dhamodaran
I turn what is happening at the AI frontier into what it means for enterprise systems, and I build AI products myself (Euliv Analytics, Vantage). I write Leading Indicator every Friday: the AI and enterprise tech moves that matter, and what they mean for you.
Views are my own and do not represent any employer or client. Graphics are original; sources are linked.